[.green-span]How to Use Machine Learning for Credit Scoring and Underwriting[.green-span]
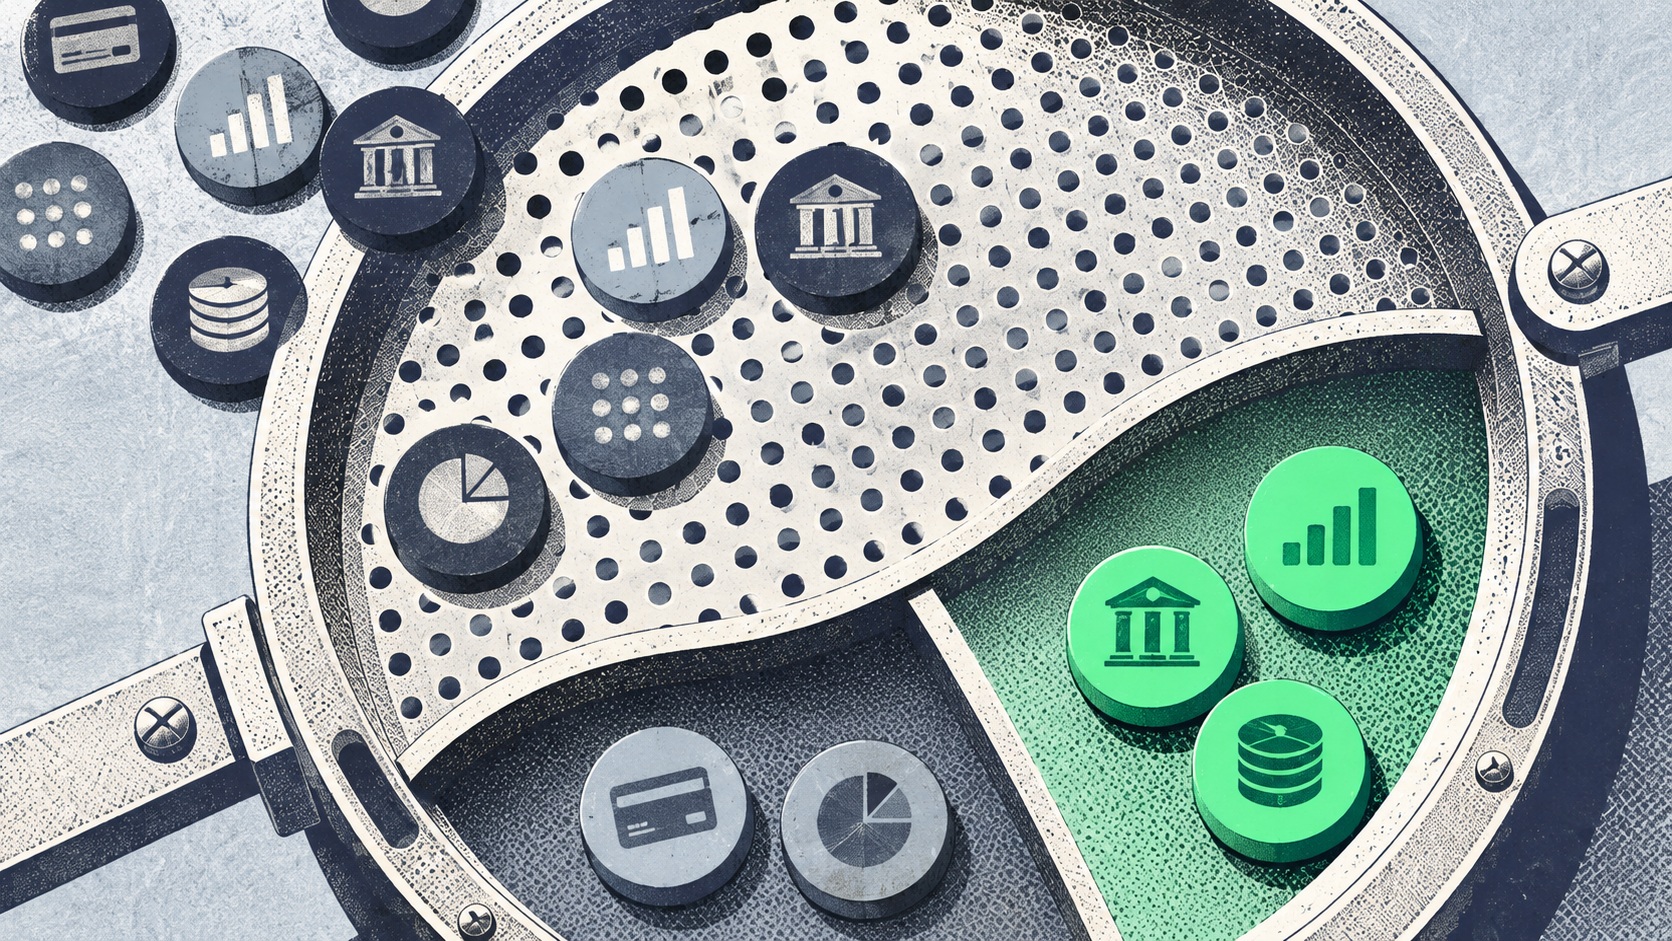
To use machine learning for credit scoring and underwriting, train a model such as gradient-boosted trees on bureau, cash-flow, and business data. Benchmark it against your current scorecard, validate it on out-of-time data, and confirm it produces specific, accurate adverse-action reasons. Then run it in shadow mode before it makes live decisions, and monitor performance and fairness for as long as it stays in production.
The payoff is measurable: a FinRegLab study of US consumer data found that machine learning models substantially outperformed logistic regression across all data types tested. The rules around those models also changed in 2025 and 2026, so credit, risk, and product leaders need a current playbook.
This guide covers the evidence, the US regulatory picture as of November 2026, a seven-step framework, and the pitfalls that stall ML underwriting projects. It is general information rather than legal advice, so confirm specific obligations with your counsel.
Machine Learning for Credit Scoring Finds Signal Scorecards Miss
Approvals rose about 4% in simulation when FinRegLab compared its strongest ML models with models built on simpler analytics at mainstream-lender risk cutoffs. The best performer in that FinRegLab consumer study combined cash-flow and credit bureau data, with models tested on new accounts opened in 2018 and 2019.
Gradient Boosting Captures Patterns That Scorecards Flatten
Traditional scorecards rely on logistic regression, which weights each variable separately and depends on analysts to hand-build interactions between variables. Tree-based methods learn those interactions directly from the data, such as how the risk of high utilization changes when monthly income is volatile. One widely used example is XGBoost, which its creators describe as a scalable tree boosting system.
Gains vary by product, data, and time period, so a lift in one study does not guarantee the same lift in your portfolio. In a peer-reviewed study of US mortgage data through 2013, random forest beat a nonlinear logit by 0.8% in AUC and 5.1% in average precision.
The same study found that Black and Hispanic borrowers were disproportionately less likely to gain from machine learning. That finding is why fairness testing belongs in the build plan from day one.
Cash-Flow Data Adds Signal That Bureau Files Lack
In FinRegLab's consumer research, gains from adding cash-flow data were somewhat smaller than gains from adopting machine learning itself. Data limits also made it hard for the researchers to assess thin-file and no-file consumers, so treat claims about those segments with caution.
For small businesses, the Sharpening the Focus study from FinRegLab and NYU Stern found that cash-flow information substantially increased predictive signal. The baseline models relied mainly on owners' personal credit scores and firm characteristics. The effects were larger for low-score owners whose businesses were less than five years old.
The study drew on more than 38,000 small business loans originated by two fintech lenders between 2015 and 2024, according to the FinRegLab press release. Visa funded the research in part, and Plaid provided connectivity to the pilot programs.
FICO reports that its next-generation UltraFICO Score delivers a 7% relative increase in approvals with no incremental risk. That figure comes from FICO's own analyses, and the score is distributed through Plaid.
Explainable Decisions Keep ML Underwriting Compliant
A more accurate model still has to explain each decline in terms the applicant can understand. Under 12 CFR 1002.9(b)(2), the statement of adverse-action reasons must be specific and indicate the principal reasons. The official interpretation (comment 9(b)(2)) adds that those reasons must relate to and accurately describe the factors actually considered or scored, whatever the model.
SHAP is one attribution approach for generating reasons, assigning each feature the change in the expected model prediction when conditioning on that feature.
FinRegLab's 2023 research with Stanford researchers found that some explainability tools reliably identified the features that matter for consumer disclosures and fair-lending analyses. The same study found that no single technique or tool performed best across every regulatory task.
FinRegLab's April 2026 bank working group framework found many SHAP-based tools performed well, others did not, and warned against proxy-model methods for adverse action notices. Validate your reason codes against real declines before relying on any tool's output.
US Rules for ML Credit Models as of November 2026
The CFPB withdrew Circulars 2022-03 and 2023-03 on May 12, 2025, including the circular on adverse-action notices for decisions based on complex algorithms. The Reg B requirement for specific principal reasons remains in the regulation text, so the withdrawal leaves the core adverse-action duty in place.
On April 17, 2026, the Federal Reserve's SR 26-2 superseded and replaced SR 11-7 as model risk management guidance. SR 26-2 states that it sets no enforceable standards and is most relevant to banking organizations with over $30 billion in total assets. Its principles cover traditional statistical models and non-generative, non-agentic AI models.
Non-bank lenders sit outside its stated audience, but its lifecycle principles still give any team a practical structure for validation and monitoring.
The CFPB's Reg B final rule, published April 22, 2026, states that ECOA does not authorize disparate-impact liability. The CFPB's 2025 Fair Lending Report, published in 2026 adds that the agency no longer uses disparate impact in its fair lending supervision or enforcement. A law-firm analysis notes that the rule has no bearing on Fair Housing Act or state-law disparate impact, so fair-lending risk has not disappeared.
Where Lendflow Fits in an ML Underwriting Stack
A credit model is only as useful as the data feeding it and the workflow acting on its output. Lendflow splits that work into three layers built for embedded SMB lending, and each layer plugs into existing systems through APIs or ready-made connectors.
- Lendflow Connect links brands to a marketplace of 75+ specialty and bank lenders through a single integration, with smart waterfall rules.
- Lendflow Intelligence turns credit and business data into lending decisions using configurable decision models, and onboarding includes model configuration and testing.
- Lendflow Automate runs workflow agents, including Doc Analyzer for extracting data from bank files and Trust Score for an explainable composite risk score.
A Seven-Step Framework to Deploy ML Underwriting
Each step below produces an artifact that your risk, compliance, and partner teams can review. The validation and monitoring steps follow the lifecycle themes in SR 26-2, which non-banks can use as a voluntary structure.
1. Define the Decision and the Target
Write down the exact decision the model supports, such as approve or decline, line assignment, or pricing tier. Define "bad" precisely, including the delinquency threshold and the performance window, because every later metric depends on that label. Record who the model affects and which products it covers so validators can judge whether it is fit for purpose.
2. Assemble and Govern Your Data
Pull bureau, cash-flow, and business data for the same applicants and time periods, and document where each field comes from and how consent was captured. Remove fields that are prohibited for credit decisions, and flag variables that could act as proxies for protected characteristics. Keep a frozen snapshot of the training data so anyone can reproduce the model later.
3. Engineer Features Applicants Can Understand
Build features that map to plain-language reasons, such as average daily balance, months of positive cash flow, or recent credit inquiries. This step makes adverse-action notices easier because Reg B reasons must describe factors actually considered or scored. Avoid opaque composite features that no one can translate into a reason an applicant could act on.
4. Train a Challenger Against Your Current Scorecard
Train a gradient-boosted model as the challenger and keep your existing logistic regression scorecard as the baseline. Compare both on the same holdout data using rank-ordering measures your team already trusts, such as AUC or KS. If the challenger cannot beat the baseline on your own data, the added complexity is hard to justify.
5. Validate on Out-of-Time Data and Real Outcomes
SR 26-2 lists testing activities that include out-of-sample testing, out-of-time testing, and comparison of alternative assumptions and methodologies. Score applicants from a later period than the training data, then run outcomes analysis that compares predictions with what actually happened. Have someone outside the build team review the results and document their conclusions.
6. Test Reasons and Fairness Before Launch
Generate adverse-action reasons for a sample of declines and confirm that each reason matches the factors that drove the score. Run fairness analysis across applicant segments and, where gaps appear, compare alternative model versions. FinRegLab's 2023 research found that automated debiasing approaches produced larger fairness benefits with smaller accuracy tradeoffs than narrow, traditional mitigation strategies.
7. Deploy in Shadow Mode, Then Monitor Continuously
Run the model alongside your current process before it makes live decisions, and compare approvals, declines, and reasons side by side. After launch, SR 26-2 describes ongoing monitoring as checking whether a model performs as expected as products, clients, data relevance, or market conditions change. Set review triggers in advance, and document each retrain, override, and threshold change.
Best Practices to Keep ML Credit Models Accurate and Defensible
These practices help credit and risk teams keep ML models accurate, explainable, and easy to audit as volume grows.
- Keep a simple baseline model in production or shadow so every challenger has a clear benchmark.
- Treat vendor scores as models, since SR 26-2 says model risk principles remain applicable to vendor models.
- Test explainability output against real declines, because FinRegLab's 2023 research and a 2026 bank working group framework found tool quality varied.
- Update policies that still cite SR 11-7 or the withdrawn CFPB circulars, so your documentation reflects 2026 rules.
- Review state fair-lending laws and the Fair Housing Act with counsel, because the 2026 Reg B rule does not address either one.
- Route borderline scores and thin-file applicants to manual review until you have enough performance data.
- Report vendor-reported lifts as vendor claims, and validate them on your own applicants before changing cutoffs.
One pitfall deserves special attention: skipping out-of-time validation. A model that looks strong on randomly split data can weaken once applicant mix or economic conditions shift. Out-of-time testing exposes that weakness before launch, and ongoing monitoring catches it afterward.
Start With One Challenger Model and a Clear Audit Trail
Machine learning can improve credit scoring and underwriting, with FinRegLab research showing stronger prediction than logistic regression and added signal from cash-flow data. The gains depend on your data, your product, and how carefully you validate, explain, and monitor the model.
As of November 2026, federal guidance on ML models is thinner. The Reg B duty to give specific, accurate adverse-action reasons remains in the regulation text. Start with one challenger model, one well-governed data set, and documentation that a bank partner, examiner, or state regulator could follow end to end.
FAQs About Machine Learning for Credit Scoring
Can US Lenders Use Machine Learning for Credit Decisions?
Yes, provided the model meets the same legal duties as any other underwriting method. Reg B still requires specific principal reasons for adverse action that accurately describe the factors actually considered or scored, regardless of model type.
Do ML Models Still Need Adverse-Action Reasons After the CFPB Withdrew Its Circulars?
Yes. The CFPB withdrew Circulars 2022-03 and 2023-03 in May 2025, but the Reg B requirement in 12 CFR 1002.9 remains in the regulation text. Have compliance confirm the current wording before you finalize notices.
Does SR 26-2 Apply to Fintech Lenders?
SR 26-2 is guidance for banking organizations and is most relevant to banks with over $30 billion in total assets. It states that it sets no enforceable standards, though its validation and monitoring principles offer a useful structure for any lender.
Is Cash-Flow Data Better Than Credit Bureau Data?
The current evidence favors using cash-flow data alongside bureau data. FinRegLab's strongest consumer model combined both sources, and its small-business study found cash-flow data substantially increased predictive signal over models built on owners' credit scores.
Do Lenders Still Need to Test ML Models for Fairness?
The CFPB's 2026 Reg B rule states that ECOA does not authorize disparate-impact liability, and the CFPB no longer uses disparate impact in supervision. Fair Housing Act and state-law exposure may remain, so fairness testing is still a prudent control.
Explore how Lendflow connects the data behind faster, better-informed credit decisions. Learn More